CUDA 内存层次结构CUDA Memory Hierarchy
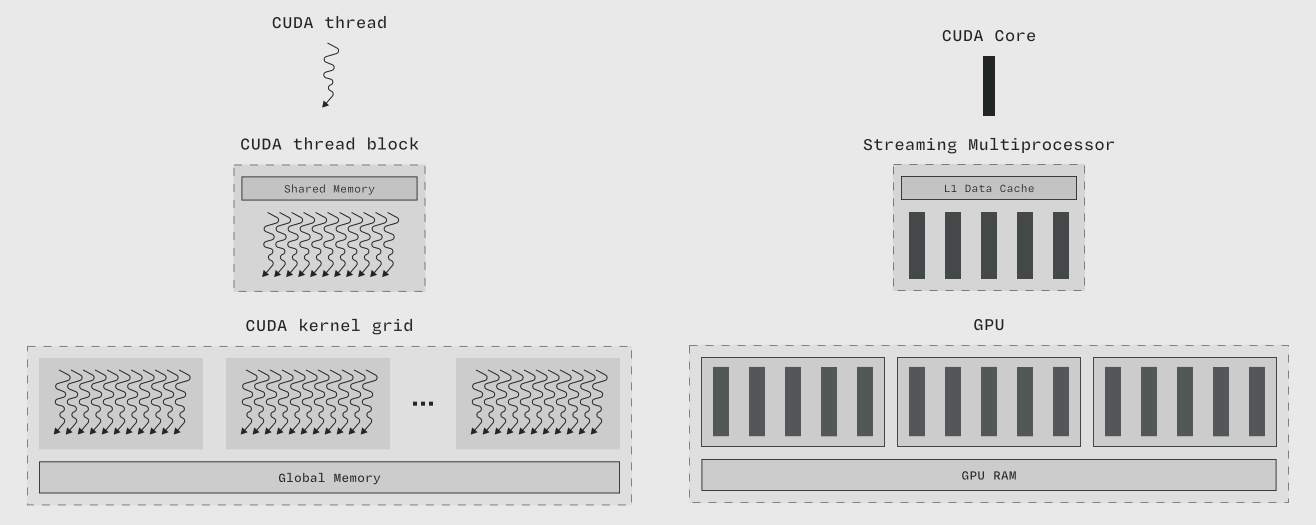
共享内存 (Shared Memory) 和 全局内存 (Global Memory) 是 CUDA 编程模型 (CUDA Programming Model) 中的两个内存层次(左图),分别映射到 L1 数据缓存 (L1 Data Cache) 和 GPU 显存 (GPU RAM)。改编自 NVIDIA 的 CUDA Refresher: The CUDA Programming Model 和 NVIDIA CUDA C++ Programming Guide 中的图表。
作为 CUDA 编程模型 (CUDA Programming Model) 的一部分,线程层次结构 (Thread Hierarchy) 每个级别都有一块由该级别组内所有 线程 (Thread) 共享的独立内存块:即 "内存层次结构" 。该内存可用于协调和通信,并由程序员(而非硬件或运行时)管理。 作为 CUDA 编程模型 (CUDA Programming Model) 的一部分,线程层次结构 (Thread Hierarchy) 每个级别都有一块由该级别组内所有 线程 (Thread) 共享的独立内存块:即 "内存层次结构" 。该内存可用于协调和通信,并由程序员(而非硬件或运行时)管理。
对于 线程块网格 (Thread Block Grid),其共享内存位于 GPU 显存 (GPU RAM) 中,称为 全局内存 (Global Memory)。可以通过原子操作和屏障来协调对此内存的访问,但跨 线程块 (Thread Block) 之间的执行顺序是不确定的。 对于 线程块网格 (Thread Block Grid),其共享内存位于 GPU 显存 (GPU RAM) 中,称为 全局内存 (Global Memory)。可以通过原子操作和屏障来协调对此内存的访问,但跨 线程块 (Thread Block) 之间的执行顺序是不确定的。
对于单个 线程 (Thread),其内存是 流式多处理器 (Streaming Multiprocessor, SM) 的 寄存器文件 (Register File) 的一部分。根据 CUDA 编程模型 (CUDA Programming Model) 的原始语义,此内存是 线程 (Thread) 私有的,但为了在 张量核心 (Tensor Core) 上实现矩阵乘法而添加到 PTX (Parallel Thread Execution) 和 SASS (Streaming Assembler) 的某些指令会在 线程 (Thread) 之间共享输入和输出。 对于单个 线程 (Thread),其内存是 流式多处理器 (Streaming Multiprocessor, SM) 的 寄存器文件 (Register File) 的一部分。根据 CUDA 编程模型 (CUDA Programming Model) 的原始语义,此内存是 线程 (Thread) 私有的,但为了在 张量核心 (Tensor Core) 上实现矩阵乘法而添加到 PTX (Parallel Thread Execution) 和 SASS (Streaming Assembler) 的某些指令会在 线程 (Thread) 之间共享输入和输出。
而位于中间层级的 线程块 (Thread Block) 其 共享内存 (Shared Memory) 存储在每个 SM (Streaming Multiprocessor) 的 L1 数据缓存 (L1 Data Cache) 中。对此缓存的精心管理——例如,在加载新数据之前将数据加载缓存以支持 最大数量的算术运算——是设计 高性能 (High-Performance) CUDA 内核 (Kernel) 的关键技巧。
英文原文(Modal GPU Glossary)
and global memory are two levels of the memory hierarchy in the CUDA programming model (left), mapping onto the L1 data cache and GPU RAM, respectively. Modified from diagrams in NVIDIA's CUDA Refresher: The CUDA Programming Model and the NVIDIA CUDA C++ Programming Guide.](themed-image://cuda-programming-model.svg)
As part of the CUDA programming model, each level of the thread hierarchy has access to a distinct block of memory shared by all threads in a group at that level: a "memory hierarchy". This memory can be used for coordination and communication and is managed by the programmer (not the hardware or a runtime).
For a thread block grid, that shared memory is in the GPU's RAM and is known as the global memory. Access to this memory can be coordinated with atomic operations and barriers, but execution order across thread blocks is indeterminate.
For a single thread, the memory is a chunk of the Streaming Multiprocessor's (SM's) register file. According to the original semantics of the CUDA programming model, this memory is private to a thread, but certain instructions added to PTX and SASS to target matrix multiplication on Tensor Cores share inputs and outputs across threads.
In between, the shared memory for the thread block level of the thread hierarchy is stored in the L1 data cache of each SM. Careful management of this cache — e.g. loading data into it to support the maximum number of arithmetic operations before new data is loaded — is key to the art of designing high-performance CUDA kernels.
相关词条
本词条改编自 Modal GPU Glossary(CC BY 4.0)· 中文翻译 miter6/gpu-glossary-zh,MAE 整理排版。