CUDA 线程CUDA Thread
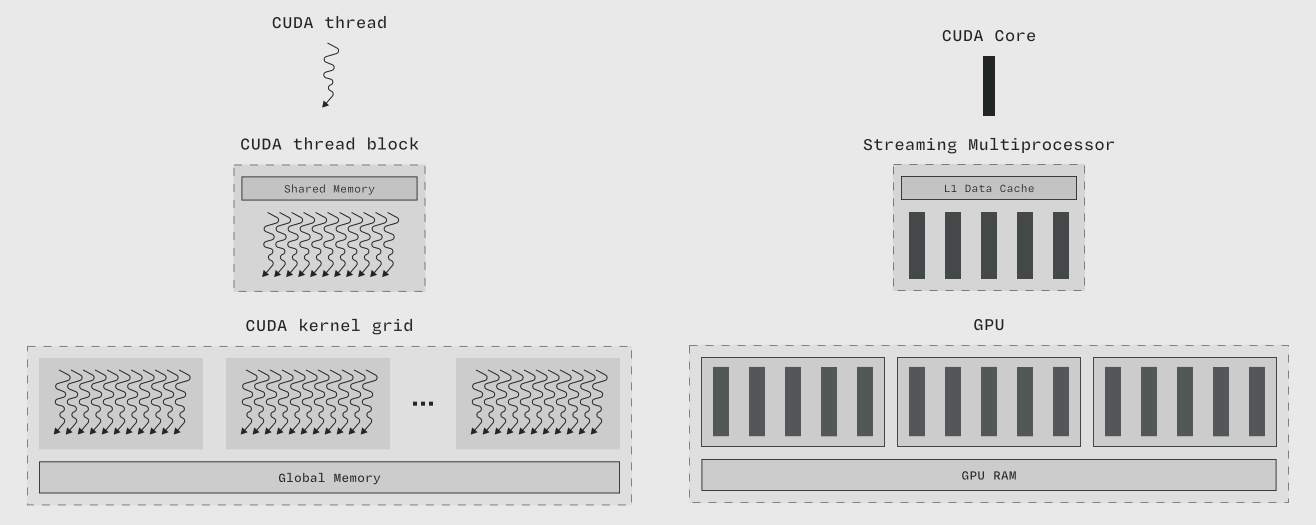
线程是线程组层次结构中的最低层级(顶部、左侧),并被映射到 流式多处理器 的 核心 上。改编自 NVIDIA 的 CUDA 复习:CUDA 编程模型 和 NVIDIA CUDA C++ 编程指南 中的图表。
_执行线程_(简称"线程")是 GPUs 编程的最小单位,也是 CUDA 编程模型 中 线程层次结构 的基础和原子单位。线程拥有独立的 寄存器,但除此之外几乎没有其他资源。
SASS 和 PTX 程序都以线程为执行目标。相比之下,POSIX 环境中的典型 C 程序以进程为目标,而进程本身是一个或多个线程的集合。与 POSIX 线程不同,CUDA 线程不用于执行系统调用。
与 CPU 上的线程类似,GPU 线程可以拥有私有的指令指针/程序计数器。但是出于性能考虑,GPU 程序通常被编写为让一个 线程束 中的所有线程共享相同的指令指针,并以锁步方式执行指令(另请参阅 线程束调度器)。
同样类似于 CPU 上的线程,GPU 线程在 全局内存 中拥有栈,用于存储溢出的寄存器和函数调用栈,但高性能 内核 通常限制这两者的使用。
单个 CUDA 核心 执行来自单个线程的指令。
英文原文(Modal GPU Glossary)
of a Streaming Multiprocessor. Modified from diagrams in NVIDIA's CUDA Refresher: The CUDA Programming Model and the NVIDIA CUDA C++ Programming Guide.](themed-image://cuda-programming-model.svg)
A _thread of execution_ (or "thread" for short) is the lowest unit of programming for GPUs, the base and atom of the CUDA programming model's thread hierarchy. A thread has its own registers, but little else.
Both SASS and PTX programs target threads. Compare this to a typical C program in a POSIX environment, which targets a process, itself a collection of one or more threads. Unlike POSIX threads, CUDA threads are not used to make syscalls.
Like a thread on a CPU, a GPU thread can have a private instruction pointer/program counter. However, for performance reasons, GPU programs are generally written so that all the threads in a warp share the same instruction pointer, executing instructions in lock-step (see also Warp Scheduler).
Also like threads on CPUs, GPU threads have stacks in global memory for storing spilled registers and a function call stack, but high-performance kernels generally limit use of both.
A single CUDA Core executes instructions from a single thread.
相关词条
本词条改编自 Modal GPU Glossary(CC BY 4.0)· 中文翻译 miter6/gpu-glossary-zh,MAE 整理排版。