全局内存Global Memory
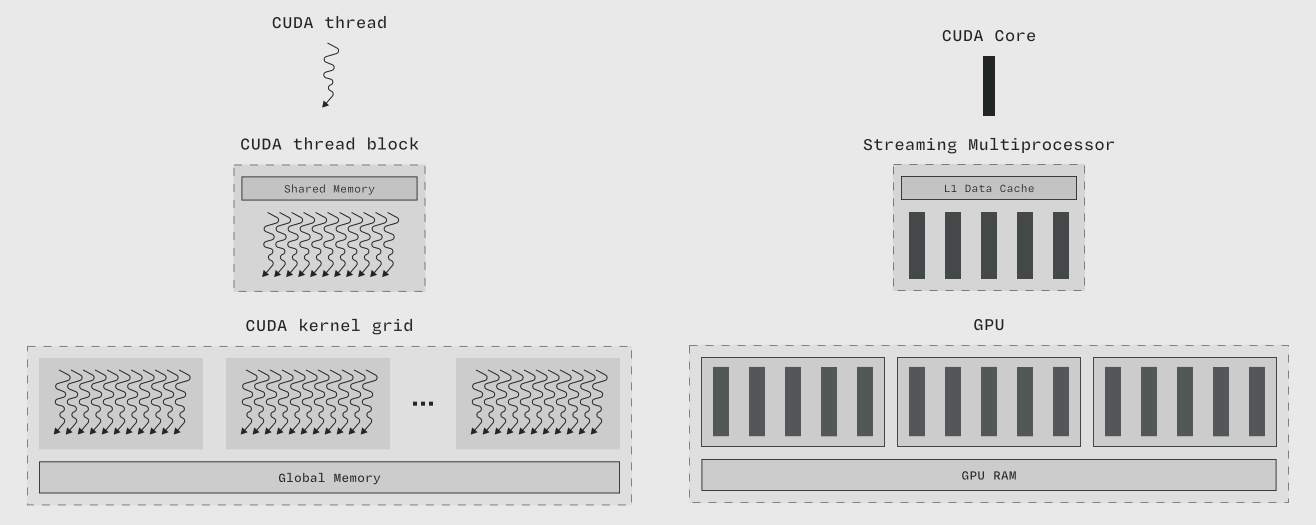
全局内存是 CUDA 编程模型 中 内存层次结构 的最高层级。它存储在 GPU 显存 中。修改自 NVIDIA 的 CUDA Refresher: The CUDA Programming Model 和 NVIDIA CUDA C++ Programming Guide 中的图表。
作为 CUDA 编程模型 的一部分,线程层次结构 的每个层级都可以访问 内存层次结构 中对应的内存。这些内存可用于协调和通信,并由程序员(而非硬件或运行时)管理。
内存层次结构的最高级别是 (Global Memory)。全局内存在其作用域和生命周期上都是全局的。也就是说, 线程块网格 中的每个 线程 都可以访问它,并且其生命周期与程序执行时间一样长。
类似于 CPU 内存的同步方式,对全局内存中数据结构的访问可以使用原子指令在所有访问者之间同步。在 协作线程数组 内,可以通过屏障等方式进行更紧密的同步。
内存层次结构 中的这一层级通常在 GPU 显存 中实现,由主机(host)通过 CUDA Driver API 或 CUDA Runtime API 提供的内存分配器进行分配。
需要注意的是,"全局" 这个术语与 CUDA C/C++ 中的 __global__ 关键字产生了冲突,该关键字用于标注在主机端启动但在设备端运行的函数(内核),而全局内存仅位于设备端。早期的 CUDA 架构师 Nicholas Wilt 在他的 _CUDA Handbook_ 中讽刺地指出,这一选择是"旨在给开发者制造最大程度的困惑"。
英文原文(Modal GPU Glossary)
in the CUDA programming model. It is stored in the GPU RAM. Modified from diagrams in NVIDIA's CUDA Refresher: The CUDA Programming Model and the NVIDIA CUDA C++ Programming Guide.](themed-image://cuda-programming-model.svg)
As part of the CUDA programming model, each level of the thread hierarchy has access to matching memory from the memory hierarchy. This memory can be used for coordination and communication and is managed by the programmer (not the hardware or a runtime).
The highest level of that memory hierarchy is the global memory. Global memory is global in its scope and its lifetime. That is, it is accessible by every thread in a thread block grid and its lifetime is as long as the execution of the program.
Access to data structures in the global memory can be synchronized across all accessors using atomic instructions, as with CPU memory. Within a cooperative thread array, access can be more tightly synchronized, e.g. with barriers.
This level of the memory hierarchy is typically implemented in the GPU's RAM and allocated from the host using a memory allocator provided by the CUDA Driver API or the CUDA Runtime API.
The terminology "global" unfortunately collides with the __global__ keyword in CUDA C/C++, which annotates functions that are launched on the host but run on the device (kernels), whereas global memory is only on the device. Early CUDA architect Nicholas Wilt wrily notes that this choice was made "for maximum developer confusion" in his _CUDA Handbook_.
相关词条
本词条改编自 Modal GPU Glossary(CC BY 4.0)· 中文翻译 miter6/gpu-glossary-zh,MAE 整理排版。