CUDA 线程层次结构是什么CUDA Thread Hierarchy
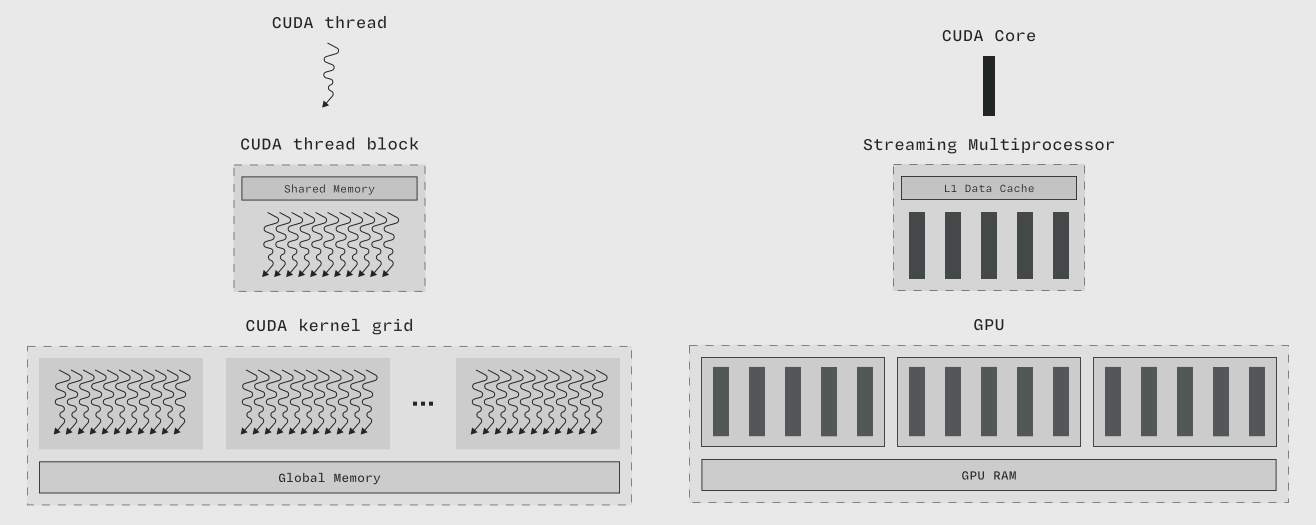
CUDA 编程模型 的线程层次结构从单个 线程 到 线程块 再到 线程块网格(左侧),映射到硬件上则从 CUDA 核心 到 流式多处理器 再到整个 GPU(右侧)。改编自 NVIDIA 的 CUDA Refresher: The CUDA Programming Model 和 NVIDIA CUDA C++ Programming Guide 中的图表。
线程层次结构是 CUDA 编程模型 的核心抽象概念之一,与 内存层次结构 并列。它通过多个层级组织并行程序的执行,从单个线程一直扩展到整个GPU设备。
层次结构中最底层是单个 线程。与 CPU 上的执行线程类似,每个 CUDA 线程 执行一系列指令 (a stream of instructions) 。负责执行算术和逻辑指令的硬件资源称为 核心 或有时称为 "流水线"。线程由 线程束调度器 选择执行。
中间层级由 线程块 组成,在 PTX 和 SASS 中也称为 协作线程数组。每个 线程 在其所属的 线程块 中都有唯一标识符。这些标识符基于索引,便于根据输入或输出数组的索引为线程分配任务。一个块内的所有线程会被同时调度到同一个 流式多处理器 (SM) 上。它们可以通过 共享内存 进行协调,并通过屏障进行同步。
在最高层,由多个 线程块 被组织成一个跨越整个 GPU 的 线程块网格。线程块 在协调和通信方面受到严格限制。网格内的块以并发方式执行,没有固定的执行顺序。CUDA 程序 必须确保块的任何执行顺序(从完全串行到完全并行)都是有效的。这意味着 线程块 之间不能通过屏障同步。与 线程 类似,每个 线程块 都有一个唯一的、基于索引的标识符,以支持基于数组索引的分配任务。
这种层次结构直接映射到 GPU 硬件: 线程 在单个 核心 上执行, 线程块 被调度到 SM 上, 而 网格 则利用设备上所有可用的 SM。
英文原文(Modal GPU Glossary)
spans from individual threads to thread blocks to thread block grids (left), mapping onto the hardware from CUDA Cores to Streaming Multiprocessors to the entire GPU (right). Modified from diagrams in NVIDIA's CUDA Refresher: The CUDA Programming Model and the NVIDIA CUDA C++ Programming Guide.](themed-image://cuda-programming-model.svg)
The thread hierarchy is a key abstraction of the CUDA programming model, alongside the memory hierarchy. It organizes the execution of parallel programs across multiple levels, from individual threads up to entire GPU devices.
At the lowest level are individual threads. Like a thread of execution on a CPU, each CUDA thread executes a stream of instructions. The hardware resources that effect arithmetic and logic instructions are called cores or sometimes "pipes". Threads are selected for execution by the Warp Scheduler.
The intermediate level consists of thread blocks, which are also known as cooperative thread arrays in PTX and SASS. Each thread has a unique identifier within its thread block. These thread identifiers are index-based, to support easy assignment of work to threads based on indices into input or output arrays. All threads within a block are scheduled simultaneously onto the same Streaming Multiprocessor (SM). They can coordinate through shared memory and synchronize with barriers.
At the highest level, multiple thread blocks are organized into a thread block grid that spans the entire GPU. Thread blocks are strictly limited in their coordination and communication. Blocks within a grid execute concurrently with respect to each other, with no guaranteed execution order. CUDA programs must be written so that any interleaving of blocks is valid, from fully serial to fully parallel. That means thread blocks cannot, for instance, synchronize with barriers. Like threads, each thread block has a unique, index-based identifier to support assignment of work based on array index.
This hierarchy maps directly onto the GPU hardware: threads execute on individual cores, thread blocks are scheduled onto SMs, and grids utilize all available SMs on the device.
相关词条
本词条改编自 Modal GPU Glossary(CC BY 4.0)· 中文翻译 miter6/gpu-glossary-zh,MAE 整理排版。