共享内存Shared Memory
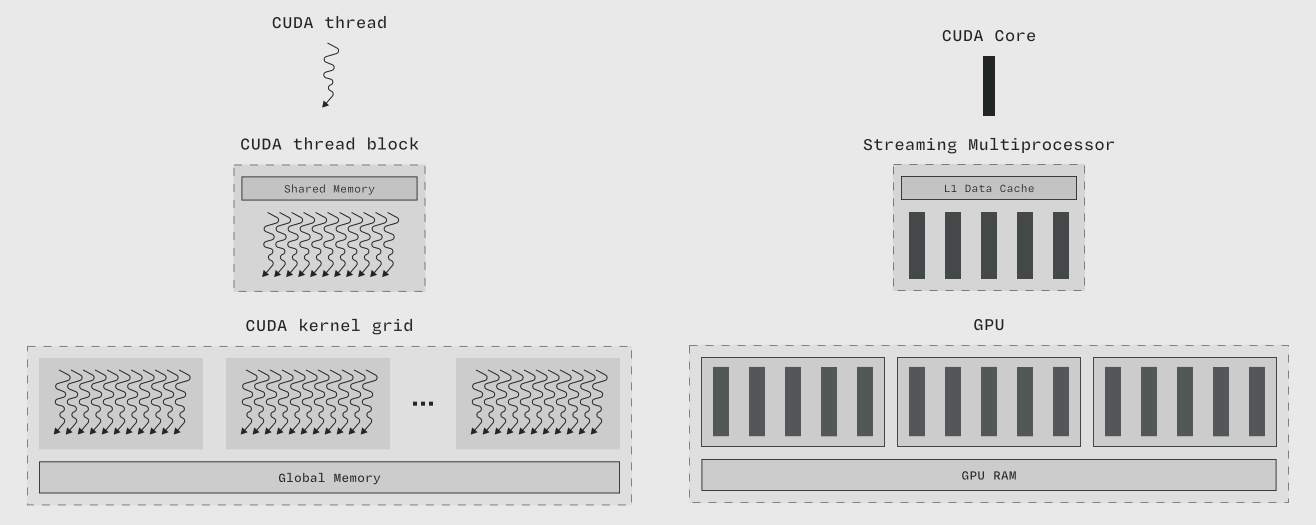
共享内存是与 CUDA 线程组层次结构(左图)中的线程块级别(左图、中图)相关联的抽象内存。改编自 NVIDIA 的 CUDA 复习:CUDA 编程模型 和 NVIDIA CUDA C++ 编程指南 中的图表。
共享内存 (Shared Memory) 在 CUDA 编程模型 中对应 内存层次结构 中与 线程层次结构 中 线程块 级别相匹配的内存层级。通常,共享内存的容量远小于 全局内存 ,但在吞吐量和延迟方面快得多。
因此,一个相当典型的 内核 通常如下所示:
- 从 全局内存 加载数据到共享内存
- 通过 CUDA 核心 和 张量核心 对该数据执行一系列算术运算
- (可选) 在执行这些操作时,通过屏障同步 线程块 内的 线程
- 将数据写回 全局内存,(可选) 通过原子操作防止跨 线程块 间的数据竞争
共享内存存储在 GPU 的 流式多处理器 (SM) 的 L1 数据缓存 中。
英文原文(Modal GPU Glossary)
level (left, center) of the CUDA thread group hierarchy (left). Modified from diagrams in NVIDIA's CUDA Refresher: The CUDA Programming Model and the NVIDIA CUDA C++ Programming Guide.](themed-image://cuda-programming-model.svg)
Shared memory is the level of the memory hierarchy corresponding to the thread block level of the thread hierarchy in the CUDA programming model. It is generally expected to be much smaller but much faster (in throughput and latency) than the global memory.
A fairly typical kernel therefore looks something like this:
- load data from global memory
- into shared memory
- perform a number of arithmetic operations on that data via the
- CUDA Cores and
- Tensor Cores
- optionally, synchronize threads within
- a thread block by means of
- barriers while performing those operations
- write data back into
- global memory, optionally
- preventing races across
- thread blocks by means of
- atomics
Shared memory is stored in the L1 data cache of the GPU's Streaming Multiprocessor (SM).
相关词条
本词条改编自 Modal GPU Glossary(CC BY 4.0)· 中文翻译 miter6/gpu-glossary-zh,MAE 整理排版。