张量内存加速器Tensor Memory Accelerator
张量内存加速器 (Tensor Memory Accelerator, TMA) 是 Hopper 和 Blackwell 架构 GPU 中的专用硬件,旨在加速对 GPU 内存 中多维数组的访问。
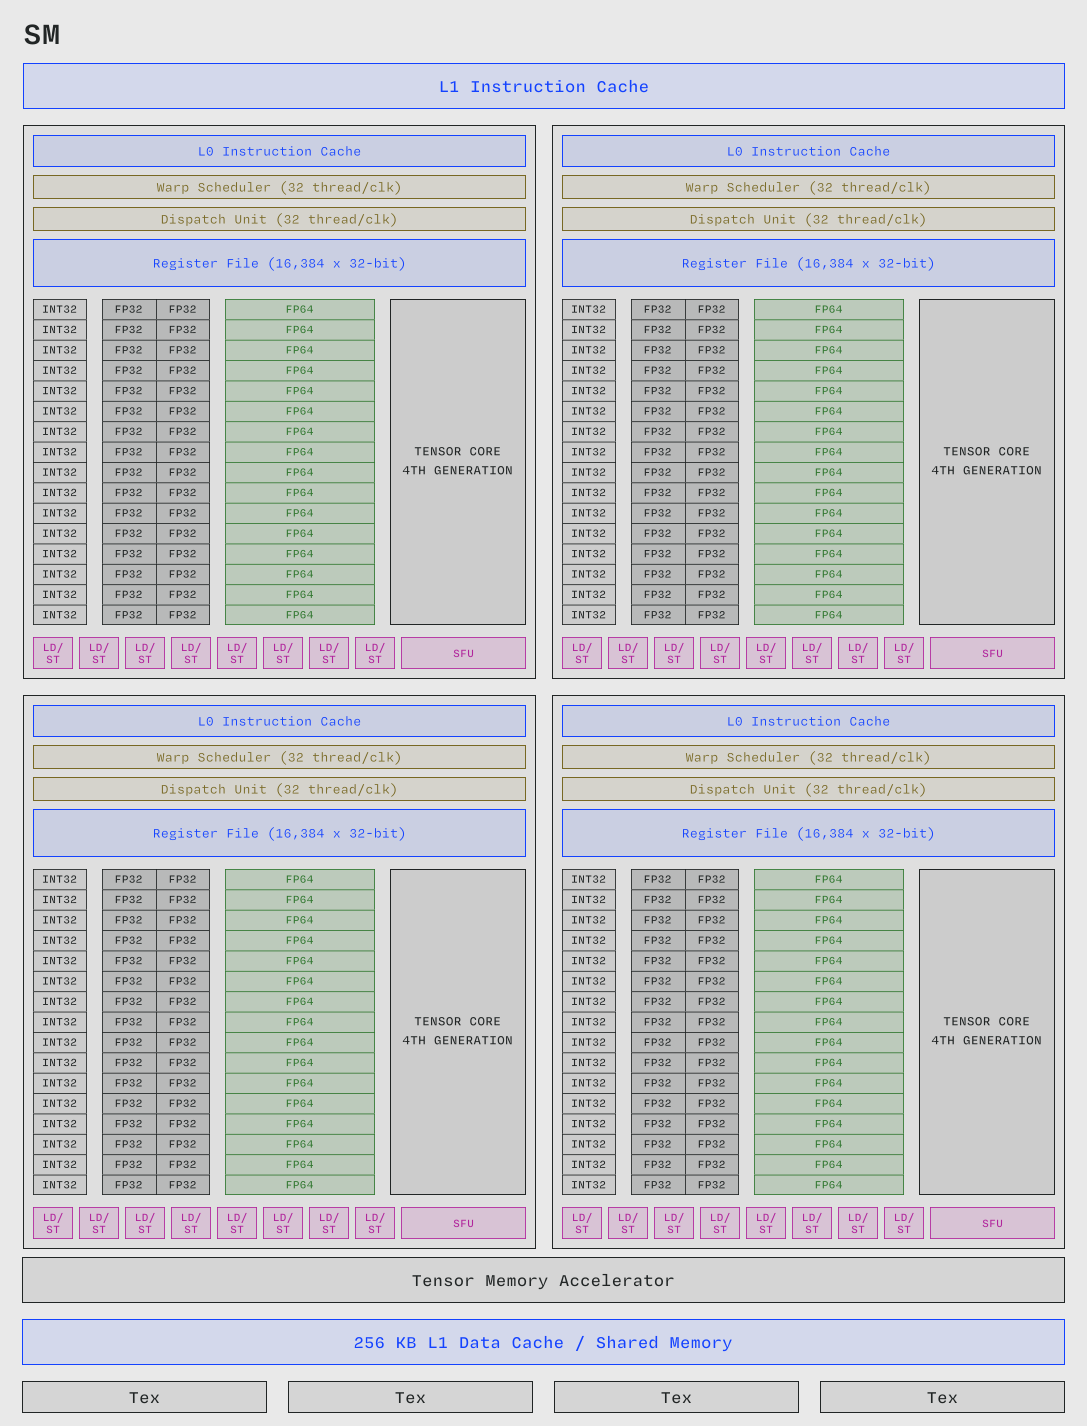
H100 流式多处理器(SM)的内部架构图。注意位于 SM 底部、在四个子单元之间共享的张量内存加速器。改编自 NVIDIA 的 H100 白皮书。
TMA 将数据从 全局内存/GPU 内存 加载到 共享内存/L1 数据缓存,完全绕过了 寄存器/寄存器文件。
TMA 的第一个优势在于减少对其他计算和内存资源的使用。TMA 硬件为批量仿射内存访问(即对许多基地址和偏移量并发执行的 addr = width * base + offset 形式的访问,这是数组最常见的访问方式)计算地址。将这项工作卸载给 TMA 可以节省 寄存器文件 空间,降低 "寄存器压力" ,并减少对 CUDA 核心 提供的 算术带宽 的需求。对于具有两个或更多维度数组的大规模(KB 级别)访问,这种节省更为显著。
第二个优势来自 TMA 拷贝的异步执行模型。单个 CUDA 线程 可以触发一个大型拷贝,然后重新加入其所在的 线程束 以执行其他工作。随后,这些 线程 以及同一 线程块 中的其他线程可以异步检测 TMA 拷贝的完成情况,并对结果进行操作(类似于生产者-消费者模型)。
有关详细信息,请参阅 Luo 等人的 Hopper 微基准测试论文 和 NVIDIA Hopper 调优指南 中关于 TMA 的部分。
请注意,尽管名称相似,但张量内存加速器并不加速使用 张量内存 的操作。
英文原文(Modal GPU Glossary)
Tensor Memory Accelerators are specialized hardware in Hopper and Blackwell architecture GPUs designed to accelerate access to multi-dimensional arrays in GPU RAM.
. Note the Tensor Memory Accelerator at the bottom of the SM, shared between the four sub-units. Modified from NVIDIA's H100 white paper.](themed-image://gh100-sm.svg)
The TMA loads data from global memory/GPU RAM to shared memory/L1 data cache, bypassing the registers/register file entirely.
The first advantage of the TMA comes from reducing the use of other compute and memory resources. The TMA hardware calculates addresses for bulk affine memory accesses, i.e. accesses of the form addr = width * base + offset for many bases and offsets concurrently, which are the most common accesses for arrays. Offloading this work to the TMA saves space in the register file, reducing "register pressure", and reduces demand on the arithmetic bandwidth provided by the CUDA Cores. The savings are more pronounced for large (KB-scale) accesses to arrays with two or more dimensions.
The second advantage comes from the asynchronous execution model of TMA copies. A single CUDA thread can trigger a large copy and then rejoin its warp to perform other work. Those threads and others in the same thread block can then asynchronously detect the completion of the TMA copy after it finishes and operate on the results (as in a producer-consumer model).
For details, see the TMA sections of Luo et al.'s Hopper micro-benchmarking paper and the NVIDIA Hopper Tuning Guide.
Note that, despite the name, the Tensor Memory Accelerator does not accelerate operations using Tensor Memory.
相关词条
本词条改编自 Modal GPU Glossary(CC BY 4.0)· 中文翻译 miter6/gpu-glossary-zh,MAE 整理排版。