协作线程数组Cooperative Thread Array
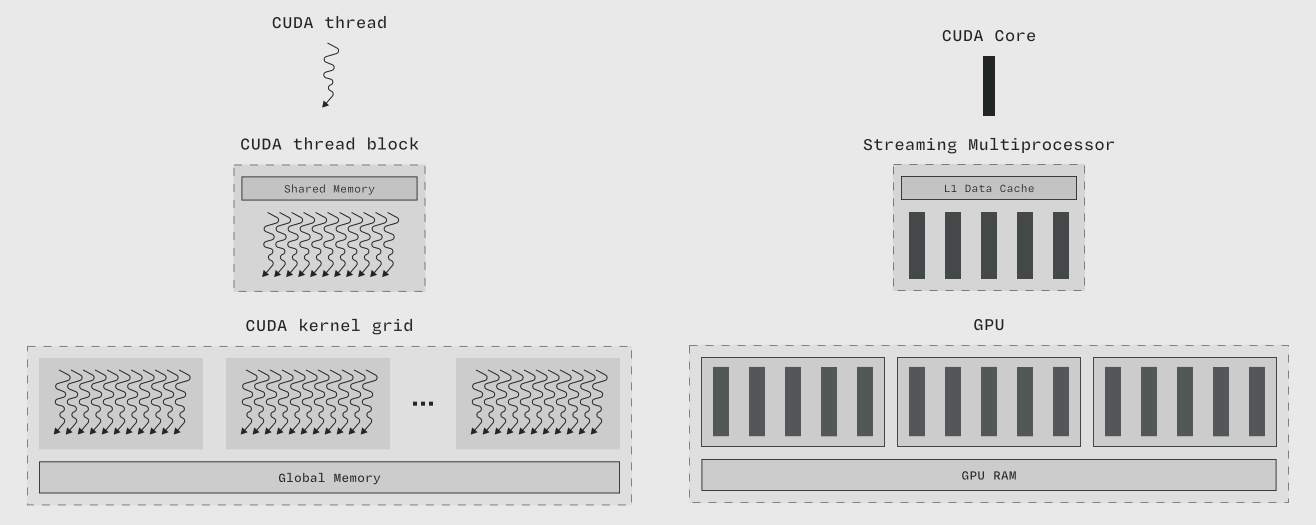
协作线程数组对应于 CUDA 编程模型 中线程块层次结构的 线程块 级别。改编自 NVIDIA 的 CUDA Refresher: The CUDA Programming Model 和 NVIDIA CUDA C++ Programming Guide 中的图表。
协作线程数组 (Cooperative Thread Array, CTA) 是被调度到同一个 流式多处理器 (Streaming Multiprocessor, SM) 上的线程集合。CTA 是 CUDA 编程模型 中 线程块 在 PTX/SASS 层面的实现。CTA 由一个或多个 线程束 (warp) 组成。
程序员可以指示 CTA 内的 线程 相互协调。
位程序员管理的 共享内存 (shared memory) 存在 SM 的 L1 数据缓存 中,这使得协作过程非常高效。 与 CTA 内的线程不同,不同 CTA 中的线程无法通过屏障相互协同工作,而必须借助 全局内存 (global memory) (例如通过原子更新指令) 来实现协作。由于驱动程序在运行时控制 CTA 的调度,CTA 的执行顺序是不确定的,一个 CTA 阻塞等待另一个 CTA 很容易导致死锁。
单个 SM 上可调度的 CTA 数量决定了 实际的占用率 (achievable occupancy),这取决于多种因素。从根本上说,SM 的资源是有限的——包括 寄存器文件 (register file) 中的行数、线程束 (warp) 的"槽位"、L1 数据缓存 中的 共享内存 (shared memory) 字节数——而每个 CTA 在被调度到一个 SM 上时,都会使用一定量的这些资源(在 编译 时计算得出)。
英文原文(Modal GPU Glossary)
level of the thread block hierarchy in the CUDA programming model. Modified from diagrams in NVIDIA's CUDA Refresher: The CUDA Programming Model and the NVIDIA CUDA C++ Programming Guide.](themed-image://cuda-programming-model.svg)
A cooperative thread array (CTA) is a collection of threads scheduled onto the same Streaming Multiprocessor (SM). CTAs are the PTX/SASS implementation of the CUDA programming model's thread blocks. CTAs are composed of one or more warps.
Programmers can direct threads within a CTA to coordinate with each other. The programmer-managed shared memory, in the L1 data cache of the SMs, makes this coordination fast. Threads in different CTAs cannot coordinate with each other via barriers, unlike threads within a CTA, and instead must coordinate via global memory, e.g. via atomic update instructions. Due to driver control over the scheduling of CTAs at runtime, CTA execution order is indeterminate and blocking a CTA on another CTA can easily lead to deadlock.
The number of CTAs that can be scheduled onto a single SM sets the achievable occupancy and depends on a number of factors. Fundamentally, the SM has a limited set of resources — lines in the register file, "slots" for warps, bytes of shared memory in the L1 data cache — and each CTA uses a certain amount of those resources (as calculated at compile time) when scheduled onto an SM.
相关词条
本词条改编自 Modal GPU Glossary(CC BY 4.0)· 中文翻译 miter6/gpu-glossary-zh,MAE 整理排版。