CUDA 设备架构CUDA Device Architecture
CUDA 全称是 _Compute Unified Device Architecture_(统一计算设备架构)。 根据上下文, CUDA 可以指代多个不同的事物: 一种 总体设备架构,或是适用于该设计架构的 CUDA 编程模型,或是扩展高级语言(如 C 语言)以添加该编程模型的 CUDA 软件平台。
CUDA 的设计愿景在 Lindholm 等人于 2008 年 发布的白皮书中进行了阐述。我们强烈推荐这篇论文,它是 NVIDIA 文档中许多观点、图表乃至特定表述的原始出处。
本文重点关注 CUDA 的 _设备架构_ 部分。 "统一计算设备架构" 的核心特点是相较于前代 GPU 架构更加简洁。
在 GeForce 8800 及其衍生的 Tesla 数据中心 GPU 之前,NVIDIA GPU 采用复杂的流水线着色器架构设计,该架构将软件着色器阶段映射到异构的、专门的硬件单元上。这种架构对软件和硬件工程师都构成了挑战:它要求软件工程师将程序映射到固定流水线中,同时迫使硬件工程师猜测流水线各步骤间的负载比例。
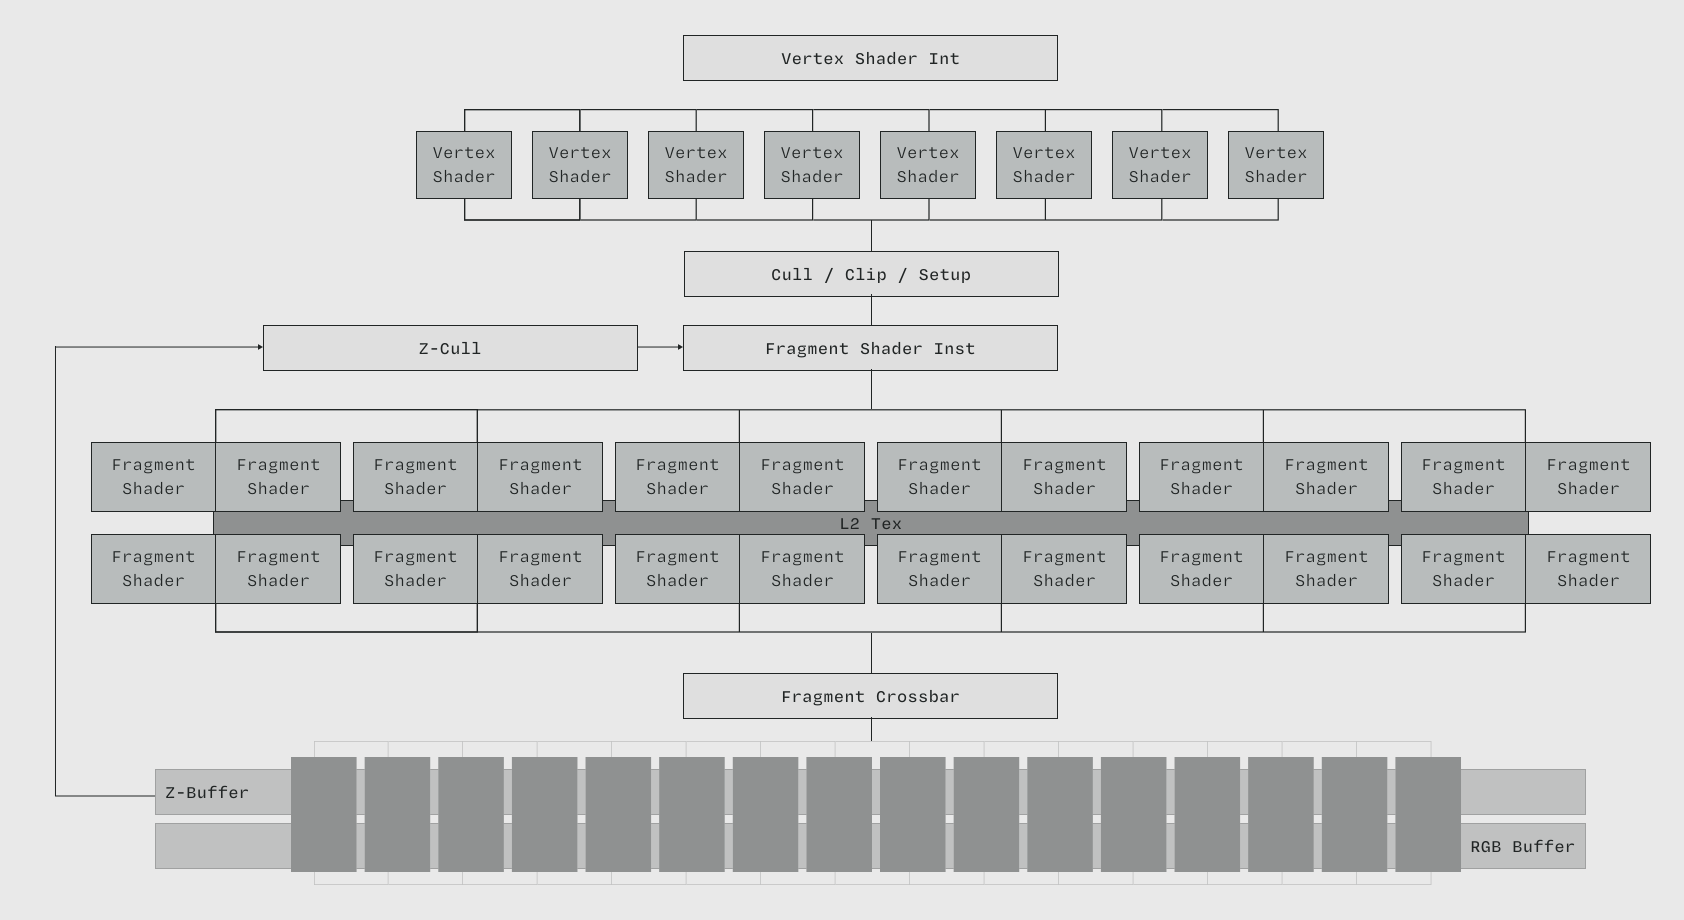 > 固定流水线设备架构 (G71) 示意图。请注意存在用于处理片段和顶点着色的独立处理器组。改编自 Fabien Sanglard 的博客。
采用统一架构的 GPU 设备则要简单得多:其硬件单元完全统一,每个单元都能够执行多种计算任务。这些单元被称为 流式多处理器 (SM) ,它们的主要子组件包括 CUDA 核心 以及(较新型号的 GPU )张量核心。
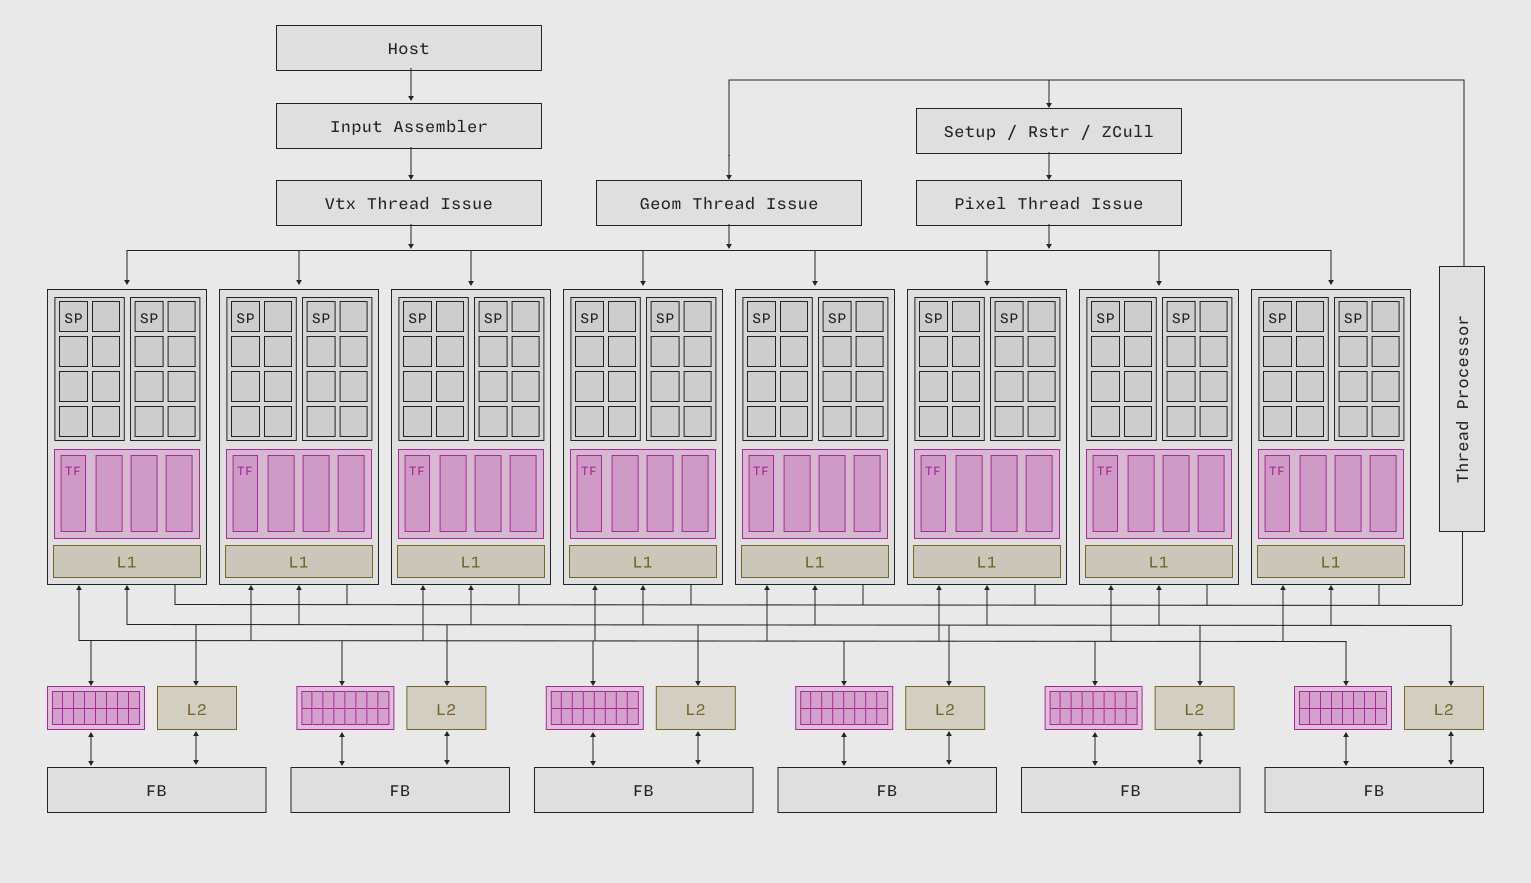 > 统一计算设备架构 (G80) 示意图。请注意图中没有区分不同的处理器类型——所有有意义的计算均由图中央相同的 流式多处理器 完成,这些处理器接收来自顶点、几何和像素线程的指令。修改自 Peter Glazkowsky 2009 年关于 Fermi 架构的白皮书。
关于 CUDA 硬件架构的历史和设计的通俗介绍,请参阅 Fabien Sanglard 的这篇博客文章。该博客文章引用了高质量的资料来源,例如 NVIDIA 的 Fermi 计算架构白皮书。此外 Lindholm 等人在 2008 年 介绍 Tesla 架构的白皮书内容详实且文笔出色。而 NVIDIA 关于 Tesla P100 的白皮书 虽学术性稍弱,但记录了对于当今大规模神经网络工作负载至关重要的一系列特性的引入过程,例如 NVLink 和 封装内高带宽内存。
英文原文(Modal GPU Glossary)
CUDA stands for _Compute Unified Device Architecture_. Depending on the context, "CUDA" can refer to multiple distinct things: a high-level device architecture, a parallel programming model for architectures with that design, or a software platform that extends high-level languages like C to add that programming model.
The vision for CUDA is laid out in the Lindholm et al., 2008 white paper. We highly recommend this paper, which is the original source for many claims, diagrams, and even specific turns of phrase in NVIDIA's documentation.
Here, we focus on the _device architecture_ part of CUDA. The core feature of a "compute unified device architecture" is simplicity, relative to preceding GPU architectures.
Prior to the GeForce 8800 and the Tesla data center GPUs it spawned, NVIDIA GPUs were designed with a complex pipeline shader architecture that mapped software shader stages onto heterogeneous, specialized hardware units. This architecture was challenging for the software and hardware sides alike: it required software engineers to map programs onto a fixed pipeline and forced hardware engineers to guess the load ratios between pipeline steps.
.](themed-image://fixed-pipeline-g71.svg)
GPU devices with a unified architecture are much simpler: the hardware units are entirely uniform, each capable of a wide array of computations. These units are known as Streaming Multiprocessors (SMs) and their main subcomponents are the CUDA Cores and (for recent GPUs) Tensor Cores.
in the center of the diagram, fed with instructions for vertex, geometry, and pixel threads. Modified from Peter Glazkowsky's 2009 white paper on the Fermi Architecture.](themed-image://cuda-g80.svg)
For an accessible introduction to the history and design of CUDA hardware architectures, see this blog post by Fabien Sanglard. That blog post cites its (high-quality) sources, like NVIDIA's Fermi Compute Architecture white paper. The white paper by Lindholm et al. in 2008 introducing the Tesla architecture is both well-written and thorough. The NVIDIA whitepaper for the Tesla P100 is less scholarly but documents the introduction of a number of features that are critical for today's large-scale neural network workloads, like NVLink and on-package high-bandwidth memory.
相关词条
本词条改编自 Modal GPU Glossary(CC BY 4.0)· 中文翻译 miter6/gpu-glossary-zh,MAE 整理排版。